Link graph mapping treats every page as a node and every hyperlink as a directed edge, turning a site into a graph you can measure instead of a folder tree you have to guess about. The payoff is diagnostic: orphan pages, authority-hoarding hubs, and disconnected topical clusters all become visible in one image. The fastest way to see this for yourself is to export a crawl and open it in a force-directed layout.
TL;DR:
- Batch fixing high-authority hub pages and removing orphan URLs on deep or isolated nodes significantly improves site crawlability and internal link flow.
- Using rendered graphs that include JavaScript-injected links provides a more accurate map of site architecture, especially for client-heavy frameworks.
- Filtering link types and crawl depths in visualizations helps identify content-rich pages and topically relevant clusters, avoiding superficial backlink or footer noise.
- Programmatic APIs with explicit responses and provenance data enable scalable, reliable link map updates and better integration into automated audit workflows.
- Moving toward graph neural network-based link prediction and evaluation helps validate interventions and reduces reliance on heuristic, guesswork-based SEO fixes.
Table of Contents
- What Is Link Graph Mapping?
- Key Graph Metrics and Topology Measures You Must Know
- Visualization Techniques That Make Graphs Interpretable
- Turning a Graph Into a Prioritized Audit Workflow
- Programmatic Mapping at Scale: Why API Design Matters
- Where Link Graph Practice Is Actually Heading
- Mapping Your Own Domain Without the Manual Grind
- Sources
- FAQ
What Is Link Graph Mapping?
A link graph is a directed graph. Pages are nodes; hyperlinks are edges pointing from the linking page to the linked page. That directionality matters. A page with a hundred inbound links and zero outbound ones behaves nothing like a page with the reverse ratio, and any analysis that ignores direction will misread both.
Two distinctions separate a useful map from a decorative one.
- Rendered vs. source graph. A source graph reflects only what is in the raw HTML. A rendered graph includes links injected by JavaScript after the page loads. Sites built on client-heavy frameworks often show a dramatically sparser source graph than rendered graph, and crawlers that never execute JavaScript will report orphans that are not actually orphans.
- Scope of the map. An internal site graph traces link flow across your own domain. A backlink neighborhood graph maps how external domains point into and around your site. A knowledge-graph link chart maps entity relationships rather than raw hyperlinks, closer to a link analysis diagram used in intelligence or investigative research than to a crawl export.
SEOs mapping internal architecture want the internal graph, almost always rendered. Researchers studying link-based reputation or citation patterns want the backlink neighborhood. Analysts building or auditing a knowledge graph are working with an entity relationship graph, not a hyperlink graph at all, even though the visualization conventions overlap heavily. Search Engine Journal's analysis of link graphs and Google rankings treats these graphs as the mechanism search engines use to assess authority and topical relevance, and to flag anomalies like silos and orphans.
Key Graph Metrics and Topology Measures You Must Know
Raw link counts lie by omission. A page with 40 inbound links from your site's footer carries a different signal than a page with 40 inbound links from body content across unrelated articles, even though both show in-degree 40. Context, not count, is what the metrics below are built to supply.
- In-degree / out-degree. In-degree counts inbound links to a page; out-degree counts outbound links from it. A page with high in-degree but low editorial relevance is often a template artifact (a footer or nav link), not a genuine authority signal.
- PageRank and centrality. These model how link equity theoretically flows through a graph. They are useful proxies for internal prioritization, not literal search-engine scores; Cambridge Intelligence's work on link analysis frames these measures as tools for identifying critical bridges and isolated nodes on a directed graph.
- Betweenness centrality. Identifies pages that act as bridges between clusters. Removing a high-betweenness page can fragment a whole section of your site into unreachable islands.
- Modularity / community detection. Groups nodes into topical neighborhoods. A well-architected site shows tight modularity that matches your intended content silos; a messy one shows clusters that ignore your taxonomy entirely.
- Depth, reachability, and path diversity. How many clicks from the homepage, and how many distinct routes exist to reach a page. Single-parent routes are fragile: break one link and the page effectively disappears from crawl paths.
Statistic Callout: Force-directed visualizations frequently produce a "mothball" effect, where navigation templates cluster densely at the graph's core while high-value deep or orphan pages, sometimes called "drifters," sit isolated on the periphery. Practitioners report higher returns from fixing those periphery drifters than from routine template link cleanups.
Visualization Techniques That Make Graphs Interpretable
Layout choice determines whether a graph reveals structure or just produces an attractive tangle. Force-directed algorithms, and ForceAtlas2 specifically, dominate site-graph visualization because they push connected nodes together and push unconnected ones apart, which naturally exposes clusters and outliers without manual arrangement. Other layouts, tree diagrams or circular layouts, work fine for strictly hierarchical data but flatten the cross-linking patterns that internal-link audits care about most.
Two visual encodings do most of the interpretive work. Sizing nodes by in-degree or PageRank makes hub pages visually obvious at a glance. Coloring nodes by modularity class or crawl depth turns topical clusters or architectural layers into distinct visual regions instead of an undifferentiated mass.
| Visualization control | What it reveals | Common tool |
|---|---|---|
| Node size by PageRank or in-degree | Which pages concentrate link equity | Gephi, PyVis |
| Node color by modularity | Topical clusters and silo boundaries | Gephi |
| Filter by link type (content vs. structural) | Editorial link patterns without nav/footer noise | NetworkX, Gephi |
| Filter by URL pattern or depth | Isolate a section or a crawl-depth band | Screaming Frog, NetworkX |
| Path tracing / shortest-path view | How authority or crawl paths reach a specific page | Gephi, PyVis |
Filtering matters as much as layout. A raw graph of a large site is mostly footer and navigation noise; filtering to content-only edges, or to a specific depth band, is what turns a hairball into something you can act on. Interactive tools add hover panels showing anchor text and link type, and shortest-path views that trace exactly how equity or crawl attention reaches a given page. WebAtlas, an open project built on NetworkX and PyVis, demonstrates this workflow directly: it converts Screaming Frog exports into browser-based interactive graphs that surface orphans, drifters, and hub concentration through PageRank-scaled node sizing.
Turning a Graph Into a Prioritized Audit Workflow
A graph is a diagnosis, not a fix. Getting from visualization to shipped changes takes a repeatable sequence.
- Diagnose. Scan the map for orphan pages (zero in-degree), deep pages (high click distance from the homepage), hub pages (unusually high in-degree), and fragile single-parent routes where one broken link severs reachability.
- Prioritize. Rank candidate fixes by estimated authority yield, editorial relevance to the linking page's topic, whether a content owner is actually available to add the link, and general feasibility.
- Generate candidates. Propose specific source-to-destination links, estimate how authority redistributes if added, and sanity-check that the new link makes topical sense rather than just numerical sense.
- Deploy in small batches. Ship a handful of link changes at a time rather than a site-wide template rewrite.
- Validate. Re-crawl after deployment to confirm the new edges are actually crawlable and appear where intended, then check for regressions elsewhere in the graph.
This mirrors the graph-first audit approach described by Sulayman Bowles's research on internal linking as a directed retrieval graph, which recommends capturing edge context (anchor text, DOM location, link type) and each page's reachability state before writing a repair plan that names a source, a destination, a placement, an owner, and an expected graph change.
Pro Tip: Resist the urge to fix everything a graph flags in one deploy. A single batch of ten to fifteen high-confidence links, followed by a re-crawl, tells you far more than a two-hundred-link overhaul where you can't isolate which change caused which effect.
Programmatic Mapping at Scale: Why API Design Matters
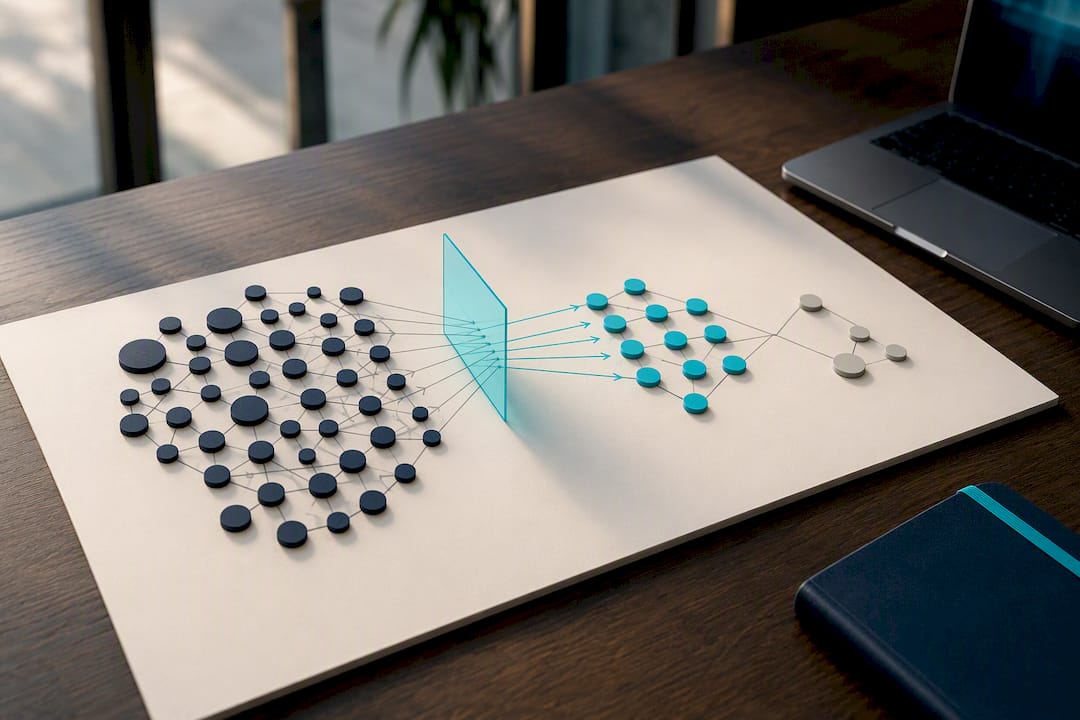
Manual crawls and desktop tools work well up to a few thousand URLs. Past that, or when mapping needs to run on a schedule, feed an automated pipeline, or support an AI agent's navigation decisions, programmatic mapping via API becomes the practical path.
The quality bar for that API output matters more than most teams expect going in.
- Typed, discriminated responses. A mapping call should tell you unambiguously whether it succeeded, partially succeeded, or failed, and why, rather than returning an empty array that looks identical to "this domain has no pages."
- Explicit failure reasons. Timeouts, blocked crawls, and render failures are distinct failure modes; treating them as the same error hides which part of your pipeline needs attention.
- Provenance and edge metadata. Knowing whether an edge came from a sitemap, a rendered page, or raw HTML lets you weight or filter it correctly downstream.
This is precisely the gap WebKnoGraph's open research framework addresses on the evaluation side, using embeddings and graph neural networks to propose candidate internal links and measuring PageRank changes and semantic coherence to judge whether an intervention actually helped. Programmatic maps built with this rigor feed cleanly into agent navigation and RAG ingestion pipelines, where a wrong or silent failure upstream corrupts everything downstream of it.
Where Link Graph Practice Is Actually Heading
GNN-based link prediction and embedding-driven recommendations are moving link graph work from manual pattern-spotting toward reproducible, testable interventions, which is a real improvement over the guesswork most audits still run on. The two mistakes I see most: treating PageRank as an absolute score instead of a modeling proxy, and over-linking navigation templates while ignoring render-only pages that a source-only crawl can't even see. When candidate links compete, favor editorial coherence and path diversity over raw authority math every time.
— Glen
Mapping Your Own Domain Without the Manual Grind
Gyrence gives you programmatic control over link graph mapping instead of stitching together a crawler, a spreadsheet, and a desktop graph tool every time a site changes. The Map primitive returns a domain's URL graph through a single typed API call, with the same discriminated-union responses and explicit failure reasons this article argues any serious mapping workflow needs, and it connects through a hosted MCP endpoint for agents that need to navigate a site graph directly.
For teams automating audits, feeding agents, or running mapping on a schedule rather than once a quarter, an API beats a manual export every time reproducibility matters. WebDoppler adds continuous monitoring on top, so you catch structural drift, new orphans, or broken hub links between audits instead of at the next one. Pricing runs on predictable metered credits, with plans starting at Standard for $75 per month. Review the plans and try a mapping call against your own domain to see the response format firsthand.
Sources
- Link Graphs And Google Rankings
- WebKnoGraph (open research project)
- WebAtlas (interactive SEO link visualizer)
- Internal linking as a directed retrieval graph — Sulayman Bowles
FAQ
What is graph mapping?
Graph mapping is the process of modeling a set of entities as nodes and their relationships as edges, then visualizing or analyzing that structure. In a website context, that means representing pages as nodes and hyperlinks as directed edges.
What is a link analysis diagram?
A link analysis diagram, also called a link chart, is a visual representation of connections between entities, most often used in investigative or intelligence work to trace relationships between people, organizations, or records. The same node-and-edge logic underlies website link graphs, just applied to hyperlinks instead of relationship data.
What is a link chart?
A link chart is another name for a link analysis diagram: a graph showing entities as nodes and their known connections as edges, typically used to surface non-obvious relationships that a table or list would hide.
What is link analysis and what is its purpose?
Link analysis is the practice of examining a network of connections to find structural patterns, such as central hubs, bridging nodes, or isolated clusters. In SEO and site auditing, its purpose is to surface anomalies like orphan pages and disconnected silos so teams can prioritize fixes that improve crawlability and authority distribution.
Do I need an API to map a link graph?
Not for a small site. Free tools like Screaming Frog handle crawls under 500 URLs, and Gephi's ForceAtlas2 layout works well for one-time analysis. For large sites, scheduled monitoring, or agent-driven navigation, an API such as Gyrence's Map primitive offers reproducibility that manual exports don't.